Reading: How We Handled Black Friday: Lessons from the Edge
Lectură: Black Friday la Nexus Retail. Citește un articol despre cum o echipă din Seattle a gestionat traficul de Black Friday. Textul ilustrează aplicarea practică a scalării.
Чтение: Опыт Черной пятницы. Прочитайте текст о том, как инженерная команда справилась с огромным трафиком. Развивайте навыки чтения и понимания текстов.
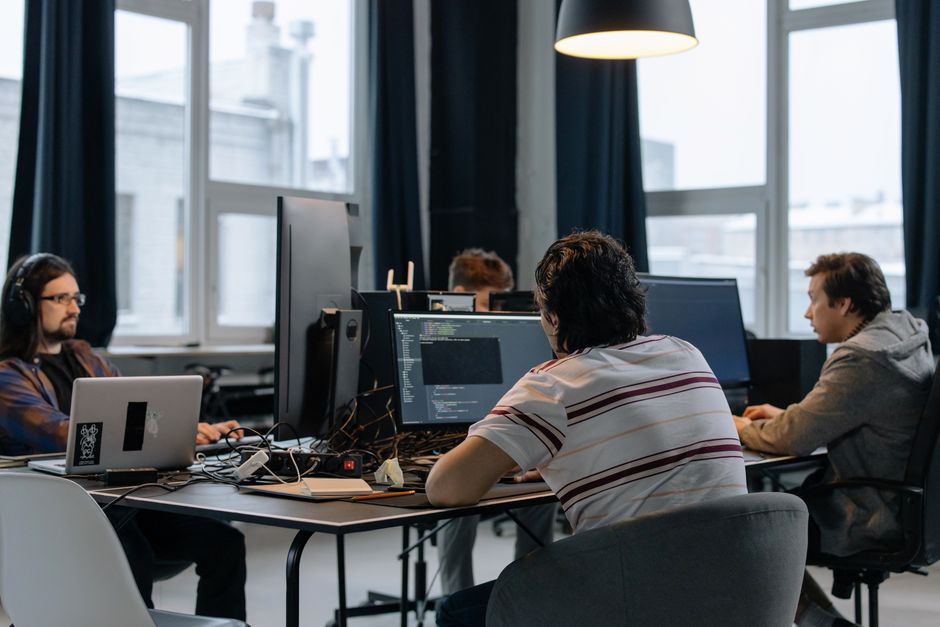
How We Handled Black Friday: Lessons from the Edge
Last November, our engineering team at Nexus Retail in Seattle faced the biggest challenge of our careers. We knew that Black Friday would bring unprecedented traffic, so we started our capacity planning back in August. Our primary goal was to ensure that the checkout service remained stable even if traffic doubled compared to last year. Supposing we failed, the company would lose millions in revenue during the busiest weekend of the entire fiscal year. We documented every decision in our design doc, outlining how we would handle the anticipated spike in demand.
First, we implemented a robust caching layer using distributed Redis clusters. This allowed us to serve ninety percent of product page requests without hitting the primary database. We also added three read replicas to handle user profile queries and inventory checks. Despite these improvements, we knew that some requests would inevitably reach the core application servers. To protect our backend from being overwhelmed, we introduced strict rate limiting and automated load shedding across all public API endpoints.
During the previous year's sale, a sudden thundering herd problem had destroyed our connection pool within minutes. To prevent this, we added exponential backoff logic and jitter to all internal service calls. Assuming that our infrastructure held up, we felt confident that our modular monolith architecture would maintain high cohesion and low coupling under pressure. We even ran extensive load tests, simulating three times our normal peak load to find any hidden hot spots in the legacy codebase.
On Friday morning at midnight, the traffic surge hit us like a tidal wave. Requests poured in from all over the country, and our CPU utilization jumped to eighty-five percent immediately. The caching layer absorbed the initial shock effortlessly, and our backpressure mechanisms successfully queued incoming requests without dropping them. We watched the metrics dashboard in real time, feeling proud of our rigorous preparation and the candor of our team during the post-mortems.
However, around two in the afternoon, we noticed a bizarre anomaly on our monitoring screens. A massive traffic spike originated not from external shoppers, but from an internal IP address belonging to our own marketing department. Their brand-new analytics dashboard was refreshing every five seconds, querying the raw database directly without using the cache. If it hadn't been for our rate limiting rules, this internal script would have saturated the database and brought down the entire checkout flow.
We quickly contacted the marketing team and forced them to use the cached reporting endpoints. The traffic immediately normalized, and the rest of the day went smoothly without any major incidents. Reflecting on the event, we realized that technical debt and human error are often much harder to manage than pure user traffic. If we were to do it again, we would add strict API keys and automated throttling for all internal analytics tools as well.
Read again and choose the right answer
When did the engineering team start their capacity planning for Black Friday?
- In January
- In August
- The week before
What protected the primary database from being overwhelmed by product page requests?
- A distributed Redis caching layer
- Turning off the website
- Asking customers to wait
What caused the unexpected massive traffic anomaly during the afternoon?
- A viral social media post
- An internal marketing dashboard refreshing constantly
- A DDoS attack from competitors
What would have happened if the rate limiting rules were not active?
- The marketing team would have been fired
- The database would have been saturated and checkout would fail
- Nothing would have changed
Sources: photo by cottonbro studio on Pexels
Despre această lecție
Această lecție de nivel B2 spre C1 este concepută special pentru inginerii software din Chișinău care lucrează cu clienți din SUA și Marea Britanie. Vei învăța cum să discuți despre arhitectura sistemelor distribuite și să folosești structuri gramaticale complexe pentru ipoteze.
Об этом уроке
Этот урок уровня B2–C1 создан для IT-специалистов из Кишинева, работающих с зарубежными клиентами. Вы научитесь обсуждать распределенные системы и использовать сложные грамматические структуры для гипотез.